The problem
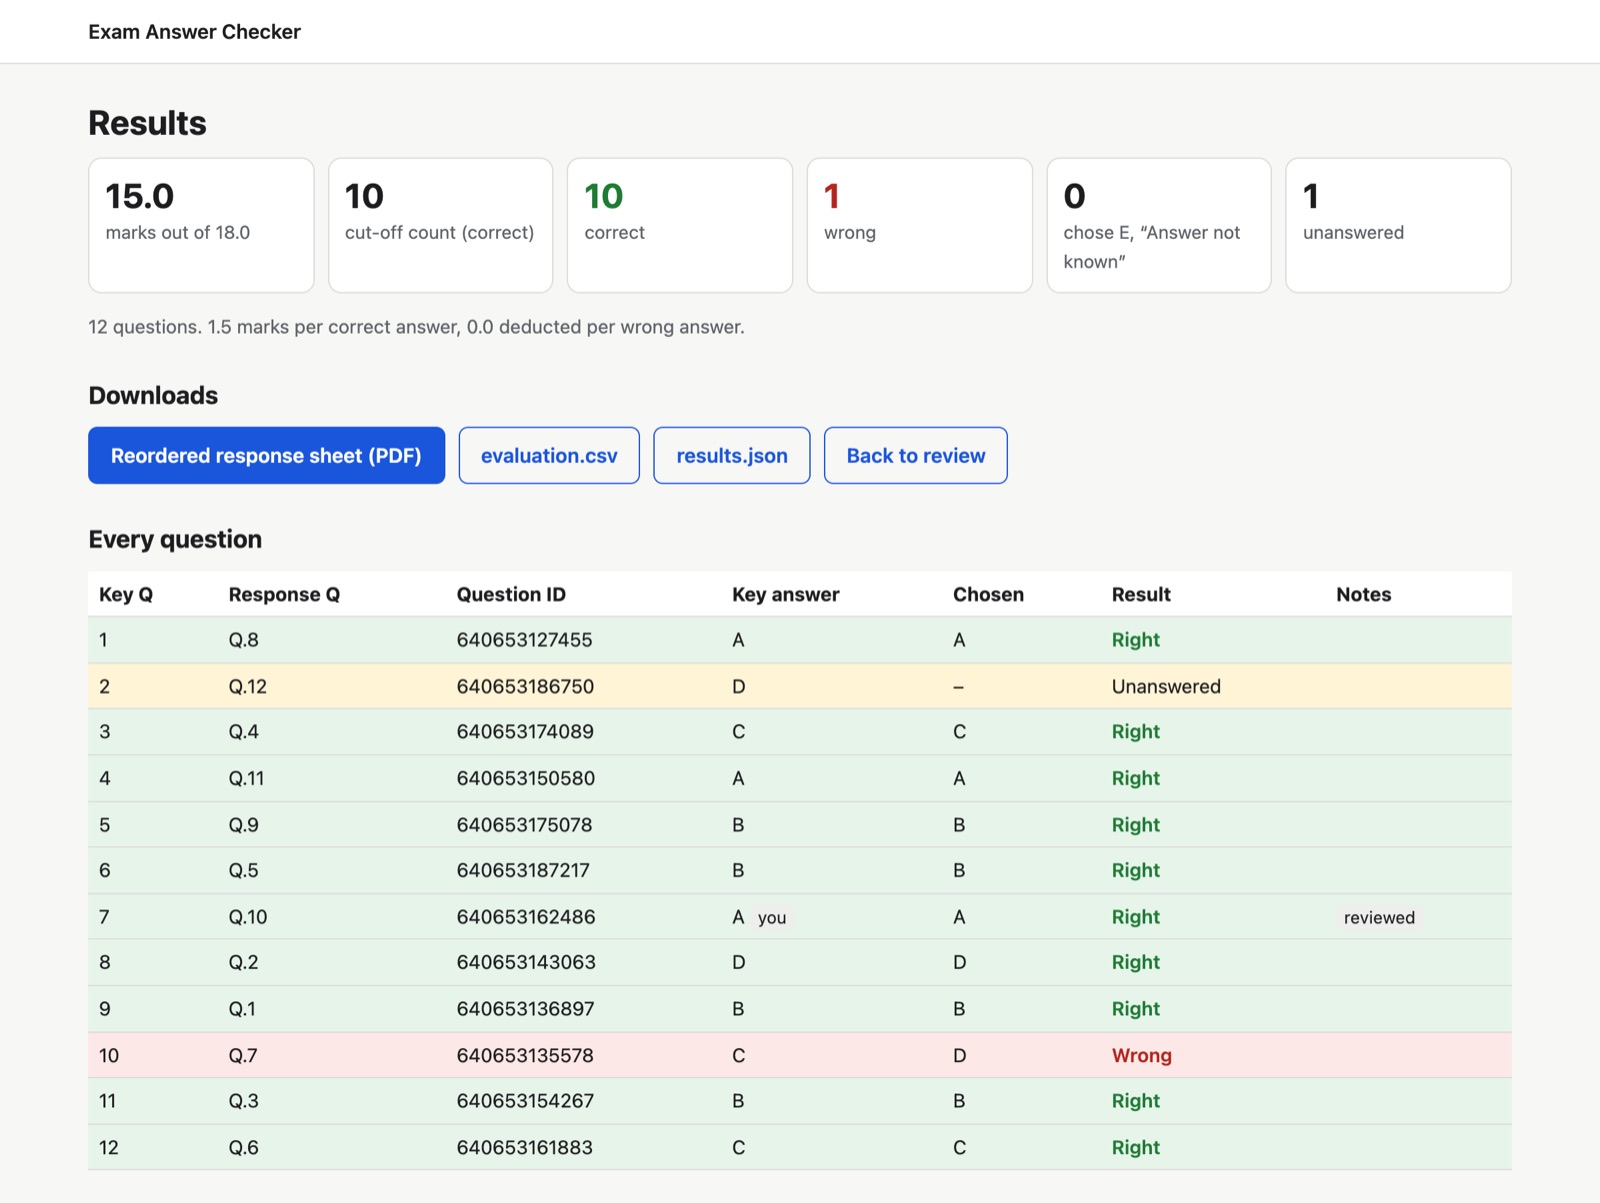
Candidates get a response sheet and a separately published answer key, but the question order is shuffled between them. Matching by number is useless; matching by hand takes hours.
My role
Solo build: OCR pipeline, matching algorithm, tick detection, API, tests and documentation.
Treat matching as an assignment problem
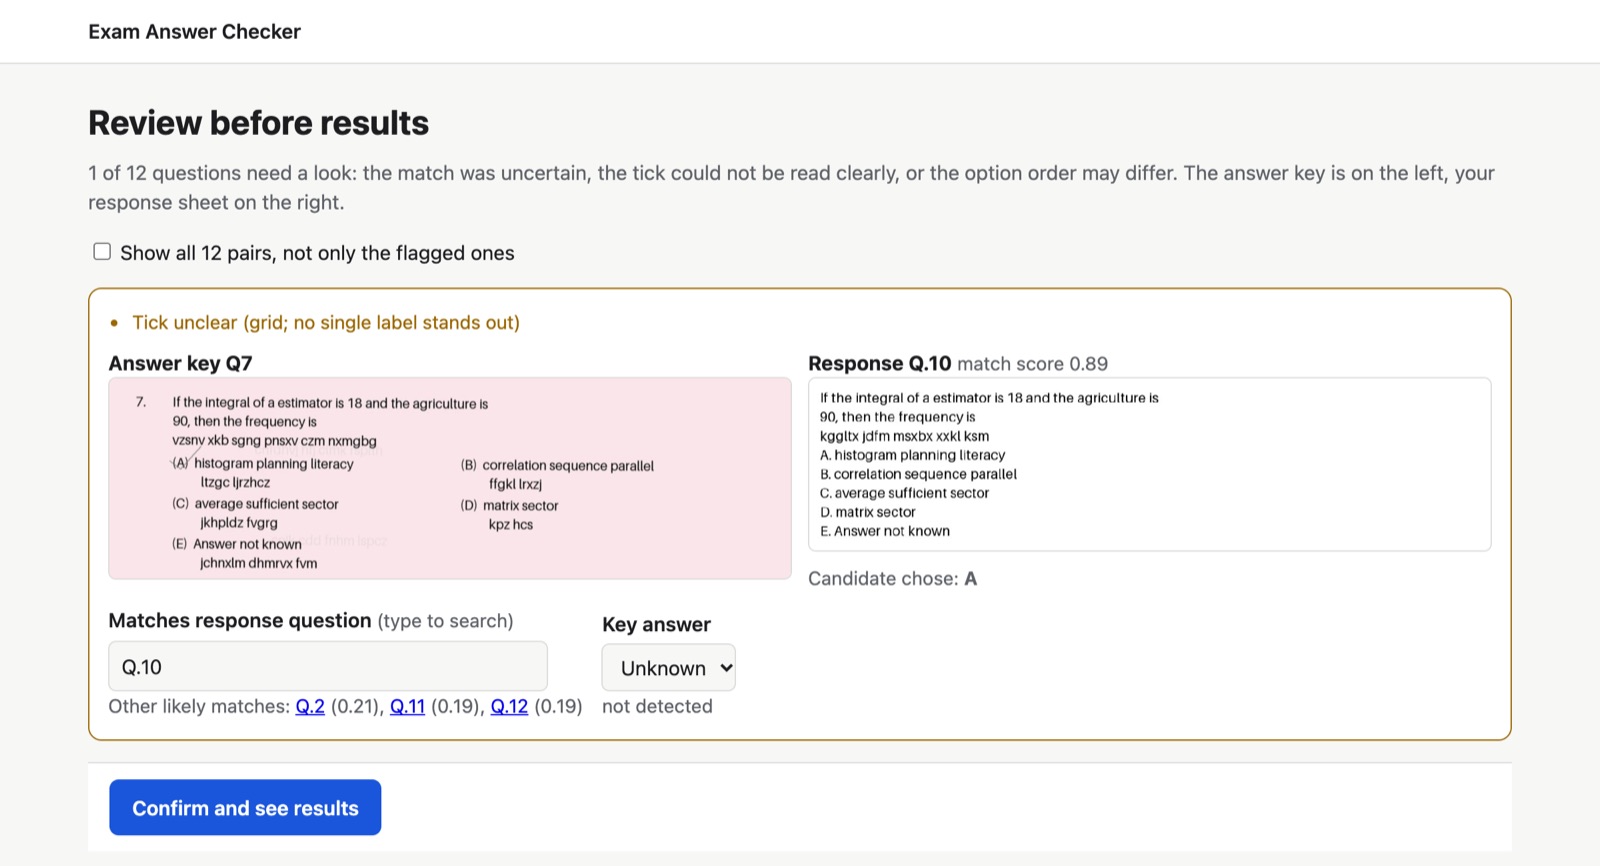
Greedy “best match per question” lets two questions claim the same answer. The Hungarian algorithm maximizes total similarity under a strict one-to-one constraint. A pair is flagged when its score is below 0.35, its lead over the runner-up is under 0.08, or the row’s best match disagrees with the assignment.
Ink signals before AI
A ticked label often OCRs as junk or vanishes, so ticks are found from three image signals, not text. One clear winner is accepted; otherwise the question is marked uncertain. An LLM fallback exists but is off by default, and anything it decides is flagged.
Built to be safe in public
PDFs are validated before processing, uploads are rate-limited, and each candidate’s data is deleted automatically after 2 hours.